Key Takeaways
- Alert severity describes the detected technique, while asset criticality describes how much the affected system matters.
- Detection tuning reduces how many alerts fire, but cannot rank the alerts that remain.
- Four context signals set an alert's real priority: asset criticality, data sensitivity, exposure and identity privilege.
- Risk-based alerting combines those signals into one accumulating risk score per user or device.
- Microsoft classifies technical criticality automatically, but business criticality must come from you, the one input a co-managed SOC provider cannot supply.
Two identical alerts arrive, one from a finance server and one from a test box, and alert triage gives them the same priority. This guide explains how asset criticality and business context decide which alerts get escalated. Detection tuning will not fix this, because the rule has no idea what the asset does for the business.
What Is Alert Triage in Security Operations?
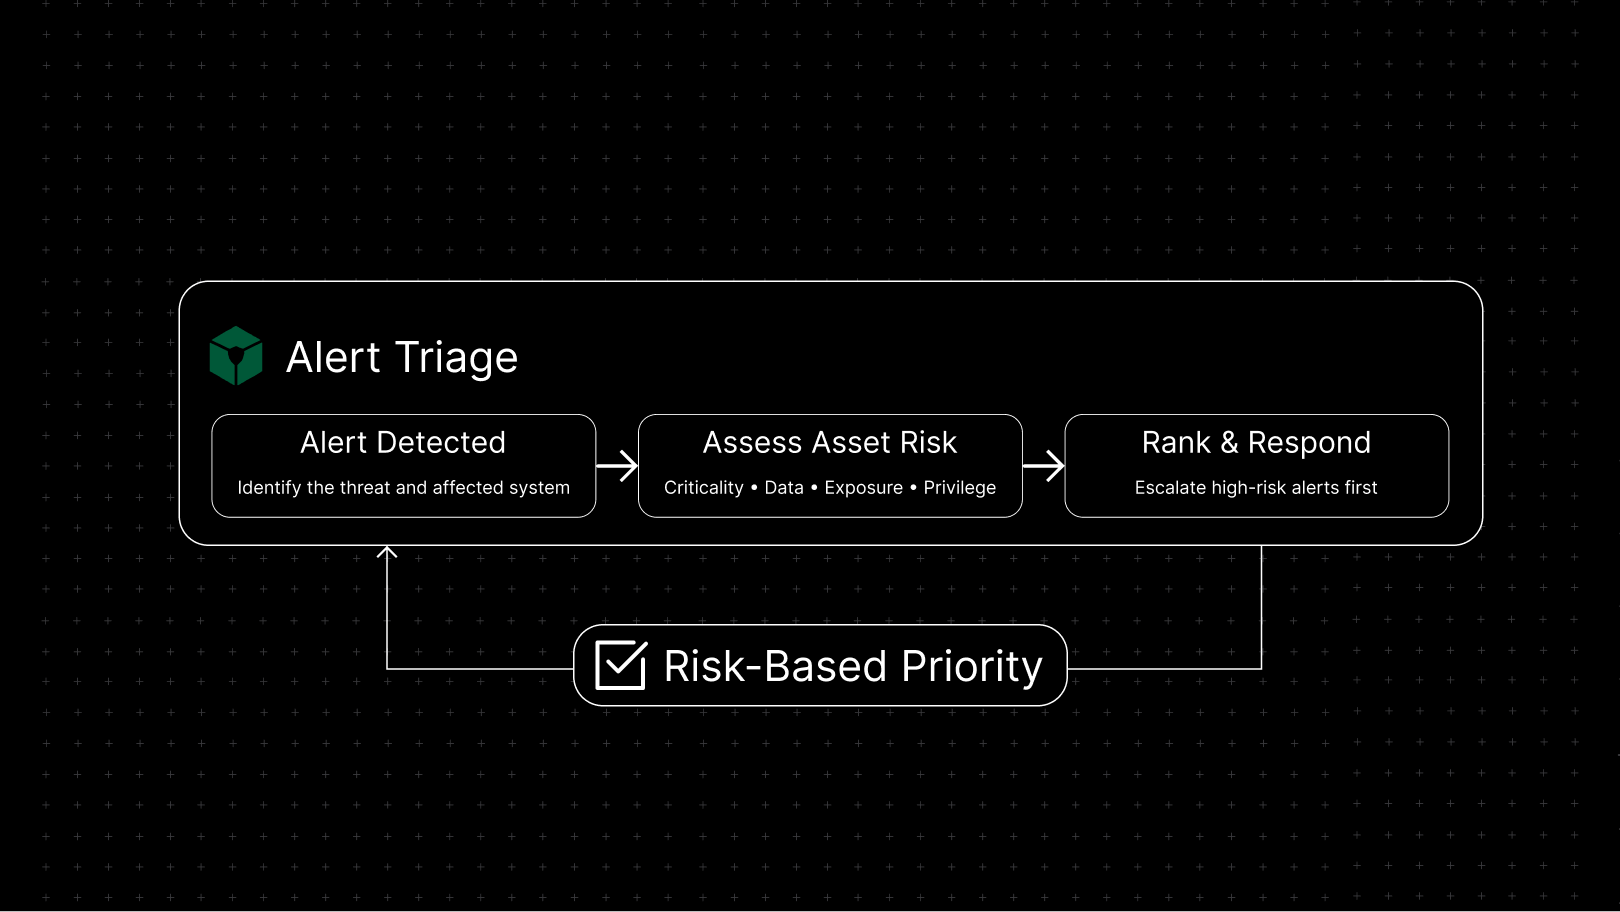
Alert triage is the process of assessing an incoming security alert to decide whether it is genuine, what it affects, and how urgently it needs a response. In a security operations center (SOC), it is the first decision made on every alert, before any investigation begins.
The alert triage process works through three questions, in order:
- Is it a true positive, meaning real malicious or unauthorized activity?
- What is affected: which system, account or data?
- How fast must we act?
Most SOC alert triage is strong on the first question and thin on the second. Detection tools describe what happened in detail, but say little about the system it happened on. To answer the second question, an analyst needs to know what the asset does, who owns it and what it can reach. They also need to know whether it is internet-facing and what data it holds.
Without that context, the analyst can only confirm that an alert is real. Every genuine alert then looks equally urgent, so the SOC triage process either escalates everything or escalates nothing. Neither outcome protects the systems the business actually depends on.
Why Alert Triage Escalates the Wrong Alerts
Most alert triage ranks alerts by detection severity, which describes the technique observed, not the value of the system it happened on.
Consider a scenario. The same impossible-travel alert fires on a finance director's account and on a contractor account limited to one shared folder. Both carry the same severity, yet one account can approve payments and the other can reach almost nothing.
Tuning does not close this gap. It changes how many alerts fire, not how the remaining alerts are ranked.
The root cause is that the SOC has detection data but no asset data. An outside provider starts with even less, because it only knows your environment once you tell it. If you are bringing one in, see what to expect in the first 60 days of a managed SOC engagement.
What Is Asset Criticality, and How Does It Differ From Severity?
Asset criticality rates how much a system, application, identity or dataset matters to the business, and it belongs to the asset, not the alert.
The two are easy to conflate. The detection vendor assigns severity. Your organization assigns criticality.
Three inputs decide criticality: the data the asset holds, the business process it supports, and its blast radius if compromised. The systems that score highest on all three are often called crown jewel assets.
Tools can supply part of this. Microsoft Security Exposure Management classifies technical criticality through predefined rules. Domain controllers default to Very High, as do privileged Microsoft Entra ID roles such as Privileged Role Administrator.
What no tool can infer is business criticality. It cannot know which app runs payroll, which server matters at quarter-end, or which contractor account belongs to a live project. Microsoft's default level for a DNS server is Low. Whether that is right for your business is a decision only you can make.
This matches NIST's criticality analysis guidance, NIST IR 8179, which prioritizes systems by their importance to organizational goals and the impact of their loss. Criticality is a business judgment first and a technical setting second.
The Four Context Signals That Change an Alert's Priority
Four pieces of context turn a generic alert into a ranked one. Together, they make alert prioritization reflect business risk rather than detection severity.
Each signal is weak on its own. Exposure alone would rank an internal server low, and criticality alone says nothing about how far an attacker could move from it. Together, they show the real stake.
Exposure also changes over time. Defender removes the internet-facing tag when a device shows no new events for 48 hours. Treat it as a live signal, not a fixed property. Data sensitivity works the same way in practice, because Defender lets analysts filter incidents by sensitivity label to find the ones involving sensitive data.
Here is an illustrative scenario. A Medium-severity alert flags a suspicious PowerShell command on a server.
- Asset criticality: the server runs payroll, and the business rates it High. Priority rises.
- Data sensitivity: it holds files labeled Highly Confidential. Priority rises again.
- Exposure: it is not internet-facing. No change.
- Identity privilege: the command runs under an account with domain admin rights, which can reach every domain-joined system. Priority rises sharply.
The alert started mid-queue on severity alone. With business context applied, it belongs at the top.
Not sure how your current alerts are ranked? Book a free consultation with CyberQuell's SOC team to talk it through.
What Is Risk-Based Alerting?
Risk-based alerting is a detection approach that adds up risk from individual detections per user or device, and alerts only when the total crosses a threshold.
Each detection becomes a risk event with a score, recorded against the entity involved. Asset criticality and identity privilege act as multipliers, so the same activity scores higher on a critical asset or a privileged account.
That is the key difference from severity-based alerting. Severity is static and assigned by the detection vendor, while a risk score is calculated from your own environment. In practice, several low-severity signals on a Very High asset can outrank one high-severity alert on a Low asset.
Because only threshold crossings become alerts, the approach also reduces alert volume, the same goal behind SOC automation.
In Microsoft environments, the closest equivalent is the incident priority score in the Microsoft Defender portal. Microsoft Sentinel's user and entity behavior analytics (UEBA) also scores anomalous activity. Both are covered later in this guide.
The scoring model is the easy half. Risk-based alerting only works if someone maintains the criticality register behind it. Without one, every asset carries the same weight and the scores mean little.
What Are the Levels of Criticality for IT Assets?
The levels of criticality for IT assets are usually four tiers: Very High, High, Medium and Low, the same model Microsoft Security Exposure Management uses.
The table below uses Microsoft's level definitions and default classifications. The last column is a suggested starting point for alert handling, not a standard.
Every Microsoft default can be changed. The table shows where Microsoft starts, not where your business should land.
The business owner assigns asset criticality, not the SOC. Keep the register small enough to maintain, because a register nobody updates is worse than none. Review it as part of change management, so a new system gets a level when it goes live.
The common failure mode is that every owner believes their system is Very High. Without someone with budget authority to arbitrate, the top tier fills up until it means nothing.
How to Apply Asset Criticality in Microsoft Defender and Microsoft Sentinel
In a Microsoft environment, asset criticality is set once in Microsoft Security Exposure Management and then feeds incident prioritization. Microsoft Sentinel watchlists cover the assets Defender cannot see.
Critical asset management in Microsoft Security Exposure Management
Exposure Management comes with predefined classifications and lets you create custom ones. Custom classifications are where business criticality goes in, and the predefined ones can be fine-tuned or switched off. You will find them under Exposure management > Critical assets in the Microsoft Defender portal. The feature is included with Microsoft 365 Business Premium and Defender for Business.
The incident priority score in the Microsoft Defender portal
Every incident receives a priority score from 0 to 100, and Microsoft lists asset criticality among its factors. The score covers Microsoft alerts, custom detections and third-party signals, and comes with an assessment that explains each result. Microsoft is moving incident handling to a new incident cases experience, currently in preview, and the priority score carries over to it.
Microsoft Sentinel watchlists and UEBA
For systems outside Defender's view, a Microsoft Sentinel watchlist holds the register. The High Value Assets and VIP Users templates, still in preview, fit this purpose and can be referenced in detection rules. Microsoft Sentinel UEBA adds an investigation priority score to anomalous activity. Criticality levels are also available in Defender advanced hunting, so custom detections can use them.
Identity context from Microsoft Entra ID
Predefined classifications already rate privileged Microsoft Entra ID roles as High or Very High. Add custom classifications for sensitive identities the predefined set misses.
If you run Microsoft Sentinel, Microsoft's security information and event management (SIEM) platform, plan around the Defender portal. Sentinel leaves the Azure portal after March 31, 2027. For help setting this up, see our SIEM and security monitoring with Microsoft Sentinel service.
Who Owns Asset Context in a Co-Managed SOC
The external SOC owns detection, the internal team owns business context, and the handover between them is where co-managed engagements tend to break down.
A provider cannot know which systems matter this quarter, which project just went live, or who changed roles last week. Only your team sees those changes as they happen.
The fix is simple to describe. Keep a criticality register the provider can read, and name one internal owner who keeps it current. That split follows the wider MSSP shared responsibility model.
The common failure is context supplied once at onboarding and never refreshed. A few months later, the provider is triaging against an environment that no longer exists. If you are still deciding whether to outsource, compare managed SOC vs traditional security monitoring.
Final Thoughts
You can keep ranking alerts by detection severity alone, or build the criticality register that makes real alert triage possible. The register is the cheaper half of the problem, and the easiest half to skip. Start with your Very High assets, name an owner for each, and let the rest follow.
Book a call with CyberQuell to review how your alerts are ranked today and where asset criticality would change what your team handles first. You can also see how our SOC monitoring and response services apply this triage around the clock.